Enterprise Restructuring in Oracle Fusion: Fixing the Foundation Without Starting Over

Your ERP is only as useful as the structure it sits on, and that structure was designed for the business you were, not the one you became. 

The ERP That Stopped Growing With the Business 

A company invests heavily in Oracle Fusion. The implementation takes about a year and goes live on the enterprise structure agreed in the first workshops. Then the business grows. A few acquisitions follow, and each new entity is fitted into the existing structure because that is the quickest way to get it to be transacted. 

Five years later, the CEO asks: “What is the profitability of each of our lines of business?” The data is all in the ERP. But the lines of business are buried so deep in a structure designed years ago that no standard report can pull them apart. So, the answer becomes: “Give us a couple of weeks.” 

The Hidden Tax on Your Business Teams 

When the structure does not match how management wants to see the business, the ERP quietly taxes your people. Managers export data and rebuild the view they need in spreadsheets, every month, quarter, and year. The pain spreads further: 

  • Collating information across ledgers and closing the books takes longer than they should. 
  • Nobody can easily see the profit or loss of goods transferred between parts of the business. 
  • Every manual step is a chance for error, and the number that reaches the boardroom is only as good as the last copy-paste. 

All this despite an ERP investment worth millions. It is why the enterprise structure deserves real thought at the start, and why fixing it later is worth the effort. 

So, Do We Have to Re-Implement? 

No. If the requirements are clear and pain points are identified, enterprise restructuring typically takes two to three months, not another 9-10 months implementation cycle. Two things make that possible: 

  • It is a structure change, not a process change. Users raise purchase orders, book sales orders and create invoices exactly as before. Only the skeleton underneath changes. 
  • It is not a people change. Nobody is being laid off. This is a restructuring inside the ERP, and you will need to say so clearly and often. 

We delivered quite a few such restructurings on a live Oracle Fusion environment in about two to three months, and leadership now gets line-of-business profitability straight from the system. 

Step 1: Start With the Pain, Not the Design 

Your business team already knows the pain points: the report that takes three days, the allocation nobody trusts, the transfer whose margin nobody can see. Trace each one back to the level of the structure that causes it: Enterprise, Ledger, Legal Entity, Business Unit, Inventory Organization or Cost Organization Structure. 

This matters because the deeper the level you change, the more objects you touch. A tweak at inventory organization level is contained. A change at ledger or legal entity level ripples through setups, balances, subledger accounting, approvals, integrations and reports. Knowing the level up front is what keeps the effort at two to three months. 

Keep it a structure change 

One principle protects this type of niche project: this is an enterprise structure change, not a business process change. Holding this line keeps training light, resistance low and scope under control. 

Step 2: Design the Structure You Wish You Had Started With 

Then ask the basic questions honestly: 

  • Will a single ledger with multiple legal entities meet our reporting and security needs? 
  • One legal entity with multiple business units, or with a single one? 
  • Do we need a shared business unit for shared services? 
  • Should inventory organizations be combined or kept separate by line of business? 

There is no universal right answer. The right answer is the one that lets leadership see profitability the way they think about the business, while still meeting statutory needs. And hold one principle: this is an enterprise structure change, not a business process change, which keeps training light and resistance low. 

If goods move between lines of business at a profit, consider enabling Financial Orchestration. It tracks profitability across intercompany and internal transfers, so each line of business shows what it really earns instead of leaving that margin hidden inside the group. A restructuring is also a good moment to revisit lot uniqueness. If it was never defined during the initial configuration, define it now, so lot-controlled items stay traceable and consistent across the new structure. 

Step 3: Data Migration, Where Restructuring Is Won or Lost 

The data already lives in the ERP, so extraction is the easy part. At Orbrick, we use tailored reports that extract the data directly in the Oracle uploader format. The business can then work on it in that same format, and the SI can load it with minimal rework. The real work is converting the data to fit the new structure, whether the structure is being expanded (one entity becomes several) or clubbed (several become one). Work in three layers: configuration (approvals, Subledger Accounting and key module setups), then master data, then transactional data. 

Start with a clean cut. Close open transactions, bring clearing accounts to zero, and reconcile balances such as cost of goods sold and accruals against the pending transactions behind them. Balances nobody can explain in the old structure get harder to explain in the new one. 

Choose tools by volume: FBDI for large master and transactional data, Functional Setup Manager for configuration, ADFDI and Macros for smaller loads, and the Oracle VBS extension in Excel for objects that have no FBDI or FSM template but do have an API. 

Then rehearse. Run at least two full cycles: a process playback to expose gaps in templates, conversion rules and configuration, and a production run timed step by step, so the cutover plan rests on measured durations. Reconcile every cycle two ways: technically (records loaded versus records signed off) and by business (subledger totals tie back to control accounts). Data quality is the business’s responsibility, and for UAT, migrate 100% of the data, because samples hide the problems that only appear at real volume. 

Step 4: Integrations and Reports Must Follow 

Replace old-structure conditions in every integration mapping. For reports, create new versions restricted to the new structure rather than editing in place. Performance stays healthy, old and new data never appears side by side, and the old reports remain available to the few people who need to reconcile. 

Step 5: UAT, and the Conversation Before It 

Start with communication, not test scripts. Hearing “enterprise restructuring”, many users assume downsizing. Say plainly: this restructures how the system is organized, not the organization. Roles and day-to-day work stay the same. Then have every user run their routine transactions and the reports they depend on, so the structure is proven on real work before it reaches production. 

Step 6: Data Security: Who Sees What 

Old and new structures coexist for a while. Everyday users with access to both may post to the old one by habit and create rework, while finance leaders and a few key users need both for the first months to reconcile. Decide access role by role: most users get the new structure only, and a small named group gets both, with clear rules on who may transact and who may only view. 

Step 7: Cutover: The Plan Behind the Switch 

Cutover needs a tightly governed plan. After the cutover date there is a blackout period when the business holds off creating transactions, so users must know how to record them meanwhile and how they will be loaded after go-live. Verify and reconcile every load, and build the plan on timings measured in rehearsal, not on hope. 

Step 8: Go-Live: The Journey Starts Here 

Reconcile again against the migration strategy, clear the blackout backlog module by module, evaluate processes and data continuously, and monitor the impact: time spent on reporting, speed of the close, and visibility of profitability by line of business. 

Conclusion: Structure Is Strategy 

An ERP does not stay right just because it went live right. Businesses acquire, reorganize and change how they measure themselves, and the structure must keep pace, or your teams will make up the difference by hand. 

  • Restructuring is not re-implementation; it requires two to three months of dedicated time. 
  • Begin with the pain, trace it to the right level, and design the answer on purpose. 
  • Treat data migration, security, and cutover as the core of the project. 
  • Communicate early that this changes the system, not the workforce. 
  • Measure the outcome after go-live. 

A well-restructured ERP gives you more than one better report. It gives you a structure that can welcome the next acquisition, the next line of business and the next tough question from the boardroom, without another round of manual workarounds. The best time to get the structure right was before go-live. The next best time is now. 
What Does Your Oracle Fusion Supplier Scorecard Miss When It Only Measures Price?

One late critical part can idle a production cell for three shifts, burn six figures in expedited freight, and force a weekend of emergency sourcing. The purchase order still shows a clean unit price. That is the trap of a scorecard that only measures what is easy to extract from PO lines. 

Oracle Fusion Cloud Procurement records much of the data a balanced Supplier Performance Index needs: delivery, receipt, inspection and qualification records. The index itself is something you build on that data, and some of its measures, such as responsiveness, need extra capture. Built well, it lets you replace price-only scorecards with continuous monitoring of supply continuity. 

Price data arrives after the deal is done. It cannot warn you when a preferred supplier starts missing delivery windows, failing inspection lots, or going quiet on RFQs. Many of the events that reveal those problems already sit in purchase orders, receipts, inspections and qualification questionnaires inside Fusion. The bigger gap is not missing data. It is the habit of treating price as the only number that matters for supplier risk and performance management in Oracle Fusion Cloud Procurement. 

Why do price-only scorecards persist after go-live? 

Transaction systems make unit price the default field because it is the simplest value to pull from a purchase order. Finance needs a savings story for the annual budget cycle, so dashboards stay glued to negotiated rate and price variance. That loop is comfortable. It is also incomplete. 

Annual performance reviews reinforce the pattern. The meeting pack asks for negotiated savings, not day-to-day delivery reliability or quality trends. Category managers prepare slides around what closed on the PO, not what arrived late, short, or defective. When the only formal checkpoint is a yearly review, lagging price data becomes the entire conversation. 

After go-live, many teams never configure the qualification and analytics pages that would surface other signals beside price. Redwood landing pages and OTBI content sit unused while buyers keep working from the same spreadsheet habits they had before Fusion. Qualification rule sets remain at default. Supplier Profile Management holds status history that nobody opens during sourcing. The system is live. The scorecard is still a price column. 

The result is predictable. A supplier can drift into late deliveries or rising defect rates for months before anyone notices, because the only number reviewed is price variance. Risk events surface only after they have already disrupted production. By the time the issue reaches the board, you are explaining expedites and line stoppages instead of showing an early warning that was already in the receipt and inspection data. 

So why does the habit stick? Because price is easy, savings are political, and continuous monitoring takes deliberate configuration. None of that means the richer signals are absent. It means your post-go-live operating model never made them visible next to unit cost. If you want Strategic Spend Control and a real Improve Supplier Performance Index, the first step is admitting that a price-only scorecard is a reporting convenience, not a risk model. 

What does a balanced Supplier Performance Index contain? 

A balanced Supplier Performance Index uses four groups of measures. Fusion does not ship this index as a standard report, so you design it. Two groups come from transactions your team already posts every day. The others need a deliberate decision about how they are captured. 

On-time delivery and quantity accuracy come from purchase order receipts and advance ship notices. You can see promised date versus actual receipt, ordered quantity versus received quantity, and patterns by site or item. Those fields already drive three-way match and inventory accuracy. They also tell you whether a low-price supplier is quietly taxing operations with chronic lateness. 

Quality metrics come from inspection results and defect records entered during receiving. Lot failures, return-to-vendor counts, and recurring nonconformances belong in the index next to price. A supplier that wins on unit cost and loses on scrap is not a win. Fusion already captures those inspection outcomes when quality processes are active. 

Track this as Supplier Quality Compliance. Orbrick measures it as the purchase order inspection ratio, supplier by supplier. When a supplier’s compliance drops, four things follow: 

  • The risk of receiving poor-quality material rises, which means rework and delays. 
  • Production becomes less reliable and downstream processes get disrupted. 
  • Procurement and operating costs go up through extra inspections and supplier follow-ups. 
  • It signals a supplier performance problem that needs corrective action or a fresh vendor evaluation. 

Responsiveness is the hardest group to fill. How long does it take to get a complete bid back? How long does a quality or delivery issue stay open? Those cycle times are leading indicators of whether a supplier will help you when demand spikes or a part goes on allocation. But Fusion has no responsiveness measure ready to use and no supplier issue management tool. If you want this group in the index, decide how to capture it: custom reporting on sourcing response dates, a field your buyers maintain, or issue data brought in from another system through integration. 

Financial and compliance signals sit in the questionnaires and profile updates maintained through Supplier Qualification Management. Insurance, certifications, financial health answers, and policy acknowledgements update the supplier profile and stay available for sourcing decisions. They are not annual theatre if your category teams review them as live inputs to sourcing decisions. 

These dimensions are not fixed weights. Category teams must tune emphasis by commodity and risk profile. A critical raw material might weight delivery and quality heavily. An indirect service might place more value on responsiveness and compliance history. Be clear about the effort behind each one. Delivery, receipt and qualification information comes from existing transactions. Responsiveness, issue-resolution metrics and some performance assessments need additional configuration, user input, custom reporting or integration. Plan that work up front, and the index becomes a shared language for Improve Supplier Performance Index discussions at the CPO level rather than a single savings number that hides operational risk. 

What does Oracle Fusion Cloud Procurement capture, and what do you add? 

For most of the index you do not need a parallel capture process. Fusion records the delivery, receipt, inspection and qualification events during normal procure-to-pay and supplier management work. 

Oracle’s Supplier Qualification rule sets documentation explains that rule sets combine qualification areas and trigger questionnaires at registration, promotion and sourcing events. Responses update the supplier profile and remain available in the Response Repository for later sourcing and purchasing decisions. A rule set is simply one or more qualification areas that control when questionnaires go out during the supplier lifecycle. Configure the triggers once, and the repository keeps filling as suppliers move through registration, promotion and RFQ activity. 

Purchase order, receipt and invoice transactions automatically populate delivery and cost performance. When goods are received against a PO, the system already knows dates and quantities. When invoices match, cost performance is visible without a separate spreadsheet. Supplier Profile Management keeps the current qualification status and history so downstream processes can use it without re-keying answers every time a buyer opens a negotiation. 

The Redwood Supplier Qualification landing page gives teams one place to monitor pending qualifications, add OTBI KPIs and visualisations, and track action plans. That is the operational surface for continuous monitoring: who is pending, what failed and which action plans are open. Not every KPI in your index can be built in OTBI, so expect some measures to need custom reporting. 

Oracle Fusion Cloud Procurement is designed to automate procure-to-pay, sourcing and supplier management so organisations can improve supplier performance and reduce risk with built-in analytics. The product intent matches the scorecard problem: performance and risk sit next to transactional automation, not in a yearly slide deck. 

Delivery, quality and qualification signals are captured when buyers create POs, warehouses receive goods, quality inspects lots, and qualification questionnaires fire on lifecycle events. Responsiveness and issue resolution are not, so settle how you will capture them before you design the index. Your job is to wire the signals you have into an index and a monitoring rhythm, and to add the missing ones deliberately, not to invent a second source of truth. 

How do you move from annual reviews to continuous monitoring? 

Annual reviews are lagging by design. Continuous monitoring uses the same Fusion objects on a different cadence: qualification at lifecycle events, live action plans, award decisions that check performance, and analytics that show drift before the next formal meeting. 

Start with rule sets. They send qualification questionnaires at registration, promotion and sourcing events. They do not re-evaluate a supplier because its delivery or quality performance dropped, so that step sits with people. When the index shows a supplier missing an on-time delivery threshold, or a supplier changes ownership or moves into a high-risk category, the category owner starts a fresh qualification. Make that a standing rule of your review rhythm so qualification is not a once-a-year ritual. 

Use the Supplier Qualification landing page as the daily control tower. Pending evaluations, failed areas and open action plans should be visible to category owners without exporting to a shared drive. When an action plan exists, ownership and due dates belong in the same place as the qualification record. That is how you stop issues from vanishing between quarterly business reviews. 

Bring the index into the award decision. Fusion will not cut a supplier’s volume or block an award because its score fell, so make checking the current index and qualification status part of how buyers award. Suppliers under review can be given less volume until issues close. Buyers then feel the index in the moment of award, not only in a retrospective scorecard meeting. Preferred status becomes earned and current, not a permanent label from last year’s negotiation. 

Replace the static scorecard pack with procurement analytics that show trends. OTBI visualisations on the qualification landing page and standard procurement analytics cover delivery and cost. Measures that OTBI cannot build need custom reporting. Together they let you watch movement week by week. Ask a simple question in every category huddle: which suppliers are drifting on delivery or quality even while price looks fine? That question only works if the charts exist and someone owns them. 

This shift is also where post-go-live support models matter. Teams that treat Fusion as a finished project freeze configuration and keep annual habits. Teams that treat it as an operating system keep tuning rule sets and KPIs. If you need a structured path for that ongoing work, Orbrick’s approach to Oracle Fusion support and managed services is built around continuous value after go-live, not ticket volume alone. Pair that operating rhythm with a technical how-to on configuring Supplier Qualification rule sets and Redwood KPIs so configuration and governance move together. 

How do you improve procurement performance after Fusion go-live? 

Post-go-live value is not another wave of custom reports. It is standard processes that write clean performance records on every transaction, analytics that expose what price variance hides, and qualification outcomes that buyers actually use when they award. 

Standardise receiving, inspection and issue logging so every site updates the same performance fields. If one plant skips inspection codes or another records supplier issues somewhere nobody else can see, your index will lie. Process discipline is the foundation of Improve Supplier Performance Index movement. Without it, dashboards only show noise. 

Use analytics to find spend leakage and supplier quality issues that price variance alone never shows. Maverick POs, off-contract buys and chronic short shipments often sit next to attractive unit prices. When you align qualification outcomes with contract compliance, buyers are steered toward approved suppliers and rogue spend shrinks because the path of least resistance matches the preferred list. 

Demonstrate measurable movement on the Supplier Performance Index as evidence of post-go-live value realisation. Boards rarely want another slide about “system adoption.” They want to know whether strategic suppliers are more reliable, whether quality escapes are falling, and whether Strategic Spend Control is real. An index built mostly on Fusion transactions gives you that story close to the system of record for the POs. 

This is also where outcome-focused work beats hour-focused work. Orbrick is the only Oracle Cloud consulting firm operating fully on at-risk, outcome-based pricing, paid only on measurable business impact. Inside engagements that target procurement KPIs, capabilities such as Second Sight process optimization help compare live Fusion data against outcome catalogs so gaps in supplier performance monitoring show up as concrete targets, not vague recommendations. For leaders modernising how ERP supports sourcing and supply risk, the same logic applies across a broader ERP modernisation path: configure what you already own before you buy another layer of tools. 

If you are framing the full journey from discovery through demonstration of value, Orbrick’s Business Value Maximization model (Sense, Evaluate, Execute, Retrospect) keeps supplier performance work tied to persona KPIs rather than to a checklist of modules turned on. The Improve Supplier Performance Index is the scoreboard. Fusion is the data source. Configuration and operating rhythm are the work. 

Conclusion 

Oracle Fusion Cloud Procurement captures most of the signals needed to replace a price-only scorecard with a balanced Supplier Performance Index. Build the index on delivery, quality and qualification data, decide how you will capture responsiveness, surface what you can on the Redwood landing page, bring the index into award decisions, and review trends in analytics so supply risk shows up before production feels it. 

Download the free Tiny Transformations e-book for 70-plus KPIs and frameworks that help procurement teams turn existing Fusion data into continuous performance gains. 

Ready to move from price-only scorecards to a balanced Supplier Performance Index? Book a strategy session with our team. 

Why Your Enterprise AI Agent Keeps Forgetting You?

I’ve spent the last few months watching companies roll out AI agents that are, by any reasonable technical measure, impressive: they reason over multi-step tasks, call the right tools, produce competent output. And then I watch the same agent ask a user, for the third week running, what format they prefer their reports in. That gap between “sounds intelligent” and “remembers anything” is where most enterprise agent deployments quietly lose their value proposition. 

This is worth taking seriously as an architecture problem, not a UX afterthought, because the solution Oracle has built into AI Agent Studio is a genuinely different answer to it than what most of the ecosystem has settled on. 

Memory Is Not the Context Window 

The confusion starts with a category error: treating a large context window as memory. A context window is working space, what the model can see during this single inference call. Memory is what persists between calls, sessions, and, critically for enterprise use, between the different agents that might touch the same case over its lifetime. 

The obvious fix people reach for is dumping conversation history back into the prompt on every turn. It feels like memory. It behaves like something else, with specific failure modes: 

  • Signal dilution. A long troubleshooting thread might contain three facts worth carrying forward and forty turns of dead ends, clarifications, and restated context. Feeding all of it back in wastes token budget on noise. 
  • No abstraction. What a user said in one conversation doesn’t tell you what’s true of that user in general. Real memory requires extracting durable facts, not logging exchanges. 
  • No governance. Raw history has no concept of what should expire or who’s allowed to read it. In a system touching HR records or financial forecasts, that’s a compliance problem waiting to surface in an audit. 

This is roughly where the broader field has landed too: the CoALA framework and production memory layers like Mem0 and Letta all split memory into working state and durable, structured storage. Oracle’s contribution isn’t inventing that distinction; it’s building it into an enterprise application platform with governance as a first-class requirement, not something bolted on after. 

The Shape Memory Takes: A Working Taxonomy 

Across the agent memory literature, and Oracle’s own architecture, memory tends to decompose into four types, distinguished by access pattern rather than where they live. 

  • Working (short-term) memory is the active state for the current task: the goal, progress through a workflow, intermediate reasoning. It resets when the task ends or the topic shifts. 
  • Semantic memory holds durable facts: user preferences, entity data, canonical reference information. This is what should never need re-explaining. 
  • Episodic memory captures specific past experiences as compressed, outcome-focused snapshots: what was tried, what worked, where a case stands. It’s what makes handoffs between agents, or between sessions weeks apart, coherent instead of a cold restart. 
  • Procedural memory is retained know-how: reusable tool-use patterns, decision steps, learned procedures for handling a given situation. It’s the difference between an agent that answers a question and one that’s gotten better at acting over time. 

Oracle makes explicit what’s implicit in most of this literature: these aren’t four separate systems bolted together. They’re four access patterns over one underlying state. That’s precisely where bolt-on memory stacks (a vector store here, a chat-log table there, hand-rolled extraction scripts holding it together) fall apart under production load, where multi-tenant isolation, concurrent writes, and auditability become four problems instead of one. 

How This Fits Into AI Agent Studio 

Oracle AI Agent Studio for Fusion Cloud Applications (currently at the 26C release) is the design-time environment where organizations build, extend, and deploy agents, both supervisor agents, which dynamically delegate and reason across a flow, and workflow agents, which execute a defined graph with reasoning concentrated at specific AI nodes. 

Contextual memory, per Oracle’s July 2026 guide, is structured around three pillars rather than a single store. 

What the agent retains.

Short-term memory for the immediate task, long-term memory (episodic, procedural, and user preferences) for what survives across sessions. Long-term memory is inspectable and editable, not a black box. It applies to both supervisor and workflow agents, operating at AI nodes for the latter and across all interactions for the former. 

How the agent adapts.

This is the personalization layer, and Oracle’s design choice here is a sensible one: the most recent user input overrides session memory, which overrides durable memory. The system also distinguishes an ephemeral instruction (“format this as bullets, just this once”) from a durable preference. Only confirmed preferences get promoted to long-term storage, rather than every passing instruction silently hardening into a permanent rule. 

How context gets assembled.

This is the hardest engineering problem in the stack. Injecting everything the system knows overwhelms the context window; injecting too little leaves the agent asking questions it already has answers to. The resolution is semantic matching of prior sessions to the current task, combined with prioritizing structured facts over raw conversation fragments, trimmed to stay within token budgets. 

The Substrate Underneath: Oracle AI Agent Memory on Oracle AI Database 

Here’s where it gets architecturally interesting. Separately from the Fusion Applications feature, Oracle ships Oracle AI Agent Memory, a framework-agnostic Python package (oracleagentmemory, on PyPI) that gives developers building on any stack (LangGraph, the Claude Agent SDK, the OpenAI Agents SDK, WayFlow, or custom harnesses) a governed memory layer running on Oracle AI Database: Database This gives enterprise AI teams a governed memory core on Oracle AI Database, combining short-term threads with summaries and context cards, long-term durable memories with vector search, and automatic LLM-based memory extraction. 

The pitch is direct: most production agents accumulate a patchwork, a vector database for semantic recall, a relational store for structured facts, a chat log table, and hand-written extraction glue, each piece needing its own access controls, its own backup story and compliance review. Oracle’s counter-argument is that vector similarity, relational querying, and graph-aware traversal can live in one governed engine. 

That’s not a hollow claim. On the current 26.6 release, hybrid retrieval (semantic similarity, keyword precision, and metadata filtering combined) is reported at 94.4% accuracy on LongMemEval, the standard academic benchmark for long-horizon agent memory. The hybrid approach is the load-bearing detail: pure vector similarity retrieves what’s semantically close, not necessarily what’s correct for the task. A metadata filter for record type or scope is what keeps an agent from surfacing a plausible-sounding memory from the wrong customer, the wrong thread, or an expired policy. 

Memory’s New Problem: Governance 

Persistent memory is a new category of data liability, not just a new capability. If an agent misremembers something (extracts an incorrect fact, retains a preference the user never confirmed), that error doesn’t stay contained. It persists, gets retrieved again, and quietly shapes every future interaction until someone notices. A stateless agent’s mistakes are self-limiting. A stateful agent’s mistakes compound. 

Oracle treats memory lifecycle management as inseparable from the memory system itself: 

  • Retention policies with configurable time-to-live settings and automatic expiration, so nothing persists by default indefinitely. 
  • Access controls scoping which agents and users can read or write which memory types. 
  • Deterministic conflict resolution, recency-first, with full provenance tracking so any stored fact can be traced back to where it came from. 
  • Session-end consolidation that deduplicates entries, resolves conflicts, and promotes only confirmed preferences to durable storage; ephemeral instructions get discarded. 
  • Cascading deletion at scope (user, agent, or thread) so ended relationships don’t leave orphaned fragments behind. 
  • Full CRUD visibility for users, who can see what’s remembered, correct it, or request deletion. 

That last point is the actual differentiator. A memory system invisible to the person it’s remembering things about isn’t trustworthy at enterprise scale; it’s a liability with good intentions. 

Why This Is the Right Fight to Pick 

None of this is memory for its own sake. The point is compounding value: the tenth interaction with an agent should be measurably more efficient than the first, and handoffs between agents should carry real context instead of restarting from zero. 

The interesting bet Oracle is making isn’t that memory matters; everyone building serious agent infrastructure agrees on that now. It’s that memory belongs on the same governed substrate as the rest of the enterprise’s operational data, rather than as a separate service the business has to trust and synchronize on its own. Whether that bet holds up outside a benchmark remains to be seen, but as an architectural stance, it’s a more honest answer to the statefulness problem than most of what’s currently shipping. 

Fusion accounting Hub: where it fits and when to use it?

Opening:

Every organization has transactions. Sales happen, payments are received, services are delivered, claims are processed, fees are charged, and countless other business events take place every day. But a business transaction is not the same thing as an accounting entry. The real challenge begins when these transactions originate from multiple applications and need to be transformed into accurate, consistent, and auditable accounting in Oracle.

Now consider an organization where transactions come from a mix of external applications, legacy systems, industry-specific platforms, and Oracle Cloud applications. Each may have different data structures, business processes, and accounting requirements. Finance, however, still needs one consistent financial view—with accounting governed by corporate policies, traceability back to the underlying transaction, and ultimately accurate reporting in the General Ledger.

This raises a fundamental question: Where should the accounting logic live?

Should it remain in the source application? Should the transaction be sent directly to General Ledger? Should an Oracle Cloud subledger handle it? Or is there a better approach for transactions that don’t naturally fit into a standard Oracle subledger?

This is where Oracle Fusion Accounting Hub (FAH) comes into the picture.

So, what exactly is Fusion Accounting Hub?

Think of FAH as an accounting bridge between a business transaction and the General Ledger.

A source system tells us what happened—for example, a sale was made, a claim was approved, a fee was charged, or a payment was processed. But the source system may not know how that transaction should be accounted for in Oracle. This is where FAH steps in.

FAH takes the transaction, looks at the relevant information, applies the accounting rules defined by the organization, and determines how the transaction should appear in the books.

In its simplest form:

What happened? → FAH determines how to account for it → General Ledger records it.

And this is where FAH becomes particularly powerful. Instead of embedding accounting logic into every source system, organizations can bring the transaction into Oracle and use a centralized, rule-driven accounting framework to generate the required accounting.

For example, a source system may simply send:

Transaction: Insurance Claim | Amount: SAR 50,000 | Product: Motor

FAH can use those attributes and the organization’s accounting rules to determine:

Debit: Claims Expense — SAR 50,000
Credit: Claims Payable — SAR 50,000

So, FAH is not just moving transactions from one system to another. It is helping answer one of Finance’s most important questions: “This transaction happened—but how should we account for it?”

One Accounting Engine, Two Different Worlds: SLA vs. FAH

Subledger Accounting (SLA) is Oracle’s accounting engine for generating subledger journal entries based on configured accounting rules. Oracle Fusion subledgers such as Payables, Receivables and Fixed Assets use SLA as part of their accounting processes.

But what happens when transactions originate outside Oracle’s standard operational subledgers?

FAH extends SLA-based accounting capabilities to supported transactions originating from external applications and other source systems, without necessarily requiring them to pass through Oracle’s standard operational subledgers.

For example, an invoice processed in Oracle Payables follows the standard Payables accounting flow, while a transaction received from an external insurance claims system can be accounted for through FAH using configured accounting rules.

In simple terms, SLA provides the accounting engine, while FAH provides a framework for applying that accounting capability to supported external transactions. Both can generate accounting that is ultimately transferred to Oracle General Ledger.

Aspect

Subledger Accounting (SLA)

Fusion Accounting Hub (FAH)

Primary role Accounting engine Accounting framework for external transactions
Typical transaction source Oracle subledgers External applications and non-Oracle ERPs
Accounting rules Configured for the relevant subledger Configured for the Accounting Hub implementation
Transaction processing Works within the subledger’s business process Supports accounting for externally sourced transactions
General Ledger integration Transfers accounting to GL Transfers generated accounting to GL
Example Accounting for a supplier invoice in Payables Accounting for a claim received from an external claims system


One Destination, Two Different Approaches: Direct GL Integration vs. FAH

If a transaction originates outside Oracle Fusion, does it always need to pass through Fusion Accounting Hub before reaching General Ledger? Not necessarily.

In some implementations, the source system or an integration layer can generate complete, balanced accounting entries and transfer them directly to Oracle General Ledger. In other cases, the organization needs Oracle to apply accounting rules to transaction-level data before generating the accounting entries. This is where Fusion Accounting Hub can provide additional value.

The difference is not simply how transactions enter Oracle. It is where the accounting logic resides, how much accounting detail is retained, and what level of reporting and reconciliation Finance requires.

Direct GL Integration

With direct GL integration, the source system or an intermediate integration layer determines the accounting and sends journal entries to General Ledger. Oracle validates and processes the imported journals according to the applicable import and journal rules.

This approach can be suitable when the source system already determines the required debit and credit accounts, produces valid accounting entries, and provides sufficient information for the organization’s financial reporting and reconciliation needs.

Finance can use General Ledger balances, journal details, account analysis and available journal references for reporting. However, reporting on additional transaction attributes depends on the details transferred into GL and the reporting solution implemented. If the source sends only summarized journal entries, detailed analysis of the underlying transactions may require additional reporting or reconciliation mechanisms.

Fusion Accounting Hub

With FAH, the source system provides transaction data and relevant attributes. Oracle’s configured accounting rules are then used to derive the appropriate accounting entries through Subledger Accounting. The resulting accounting can be transferred to General Ledger.

FAH can also support detailed accounting analysis through Supporting References. These can capture selected transaction attributes, such as a loan application number or insurance claim reference. When configured to maintain balances, they can support additional analytical and reconciliation requirements without requiring every business-specific attribute to become a segment of the General Ledger chart of accounts.

The resulting capabilities depend on the attributes supplied by the source system and the Supporting Reference configuration. Direct GL integration can also retain journal references and support reporting, but it does not provide the same FAH subledger accounting framework for deriving accounting and maintaining configured analytical balances.

Ultimately, the choice depends on the capabilities of the source system, the accounting requirements, the level of control and traceability required by Finance, and the reporting detail the organization needs.

Quick Comparison

Aspect

Direct GL Integration

Fusion Accounting Hub

What the source provides Prepared accounting journals Transaction data and relevant accounting attributes
Where accounting is determined Source system or integration layer Configured accounting rules in Oracle
Account derivation Typically performed upstream Can be performed through Oracle accounting rules
Accounting detail Depends on the journal detail and source references transferred Can retain detailed subledger accounting linked to source transactions
Accounting rule maintenance Often managed in the source or integration layer Managed through configured Oracle accounting rules
Financial reporting GL balances, journal details and available references GL reporting plus detailed subledger accounting inquiries and reporting
Additional analytical dimensions Depends on the information transferred and the reporting design Can use Supporting References and configured analytical balances for additional transaction-level analysis
Reconciliation and audit trail Depends on source references and the reconciliation solution Supports structured source-to-accounting traceability and additional reconciliation capabilities
Best suited for Sources that already produce complete accounting and meet Finance’s reporting needs External transactions requiring Oracle-based accounting rules, detailed traceability or additional analytical capabilities

 The key takeaway: Direct GL integration can be sufficient when the source system already handles accounting effectively. FAH becomes more valuable when the organization needs Oracle to govern accounting rules and retain additional transaction-level detail for reporting, analysis and reconciliation.

Conclusion: Beyond Moving Transactions, Toward Meaningful Accounting

Every business transaction tells a story. A claim is approved, a loan is disbursed, a service is delivered, or a payment is processed. But until that transaction is translated into the right accounts, supported by the right details, and made meaningful to Finance, the accounting story remains incomplete.

That is why choosing an accounting approach is about more than moving data into General Ledger. It is about deciding where accounting intelligence should reside, how financial rules should be governed, and how much visibility an organization needs into the transactions behind its numbers.

Direct GL integration, Oracle Subledger Accounting and Fusion Accounting Hub each serve different accounting needs. The right choice depends on where transactions originate, where accounting rules should be governed, and the level of detail, traceability and reporting Finance requires.

The real value of FAH is not simply the accounting entries it generates. It is the control, consistency, traceability, and financial insight that a well-designed accounting framework can bring to an organization.

Ultimately, there is no universal answer to where accounting should happen. The right architecture is the one that meets the business’s accounting requirements without introducing unnecessary complexity.

Because successful financial transformation is not just about recording what happened. It is about ensuring that every transaction is accounted for correctly, every number can be explained, and every financial decision is supported by information Finance can trust.

And that is where accounting becomes more than a record of the past. It becomes a foundation for better decisions about the future.

Best Practices for Building on Oracle Visual Builder Studio 

A practical guide for teams: Git workflow, app design, integrations, security, CI/CD and delivery 

Oracle Visual Builder Studio (VBS) brings a low-code application builder together with Git repositories, CI/CD pipelines and agile project tools in one place. That combination lets a small team go from idea to a running application very quickly. It also makes it easy to build up problems quickly: tangled pages, painful merge conflicts, hard-coded endpoints and deployments that only one person understands. 

This guide collects the practices that make the biggest difference for teams working in VBS. Each section explains what to do, why it matters and what to avoid, with diagrams and tables you can share in team discussions or reviews. 

What this guide covers 

Section Description
1. The building blocks What each part of VBS does and who owns it
2. Project setup How to structure repositories and agree on naming
3. Git workflow Branching, merge requests, reviews and conflict handling
4. Application design Flows, pages, fragments, action chains, variables and types
5. Service connections Reusable, efficient and safe REST integrations
6. Security Roles, secrets, backend enforcement and validation
7. Environments and CI/CD Dev, test and production, plus pipeline stages
8. Testing and performance What to test, how often, and how to keep pages fast
9. Agile and documentation Issues, definition of done, README contents
10. Common mistakes Problems teams hit most often and how to fix them
11. Adoption plan and checklist A 30-day rollout plan and a team checklist

1. Understand the building blocks 

VBS is really several tools sharing one workspace. Knowing which part handles what makes every later decision easier, and helps you assign ownership on the team. 

Area What it does Your main responsibility
Visual Builder Design web and mobile apps with pages, flows, fragments, variables, action chains and service connections Keep the app modular, readable and reusable
Git repositories Store application source and record every change Branch, review and merge safely
Pipelines Build, test and deploy automatically Make releases repeatable and low-risk
Environments Targets such as development, test and production Keep settings separate and promotions controlled
Issues and boards Plan sprints and track tasks and bugs Link every change to a reason

Key idea

Low-code does not mean low-discipline. Speed comes from the visual tools. Reliability comes from the habits around them: version control, review, automation and clear structure.

2. Set up the project for the long term 

A few decisions made before anyone builds a page will save the team a great deal of friction later. 

Organize projects and repositories 

  • One VBS project per product or team. The project holds repositories, issues, pipelines and environments, so keep related work together instead of creating a new project for each small app. 
  • Give each repository one purpose. If you build an application and keep documentation, test scripts or shared configuration, place them in clearly named folders or separate repositories. 
  • Set access deliberately. Decide who can merge to the main branch, who can approve merge requests and who can trigger production deployments. 
  • Keep a short project charter. Two paragraphs describing the app’s purpose, users and owners help new members orient themselves quickly. 

Agree on naming conventions early 

Consistent names make an application readable to someone who did not build it. That person is often you, six months later. 

Item Pattern Examples
Flows Business area, lowercase orders, customers, admin
Pages Subject and purpose order-list, order-detail, customer-edit
Fragments What it displays customer-summary, page-header
Action chains Verb and outcome loadOrders, saveCustomer, showErrorMessage
Variables Noun, camelCase selectedOrder, filterStatus
Service connections System or API name crm-service, inventory-service
Branches Type and topic feature/order-search, fix/date-format
Issues Short outcome statement Users can filter orders by status

3. Make Git the backbone of your workflow 

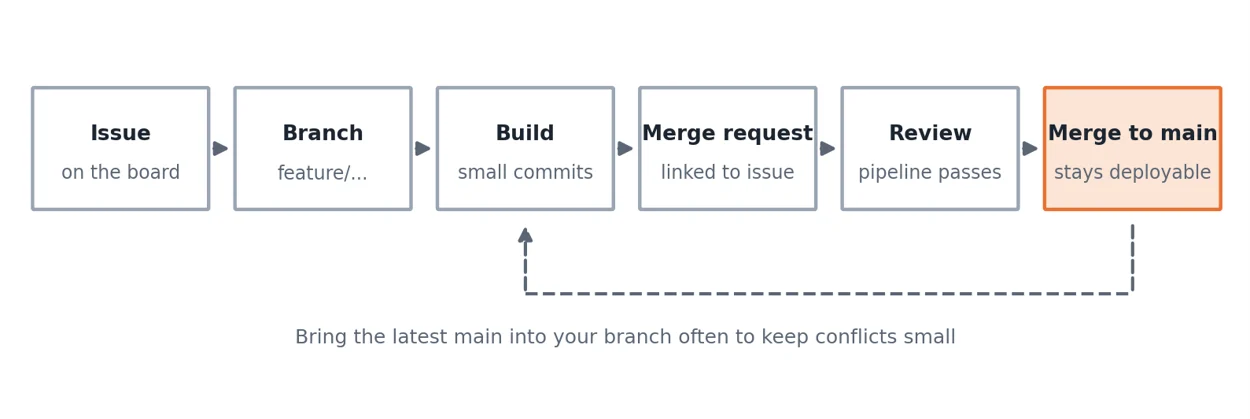
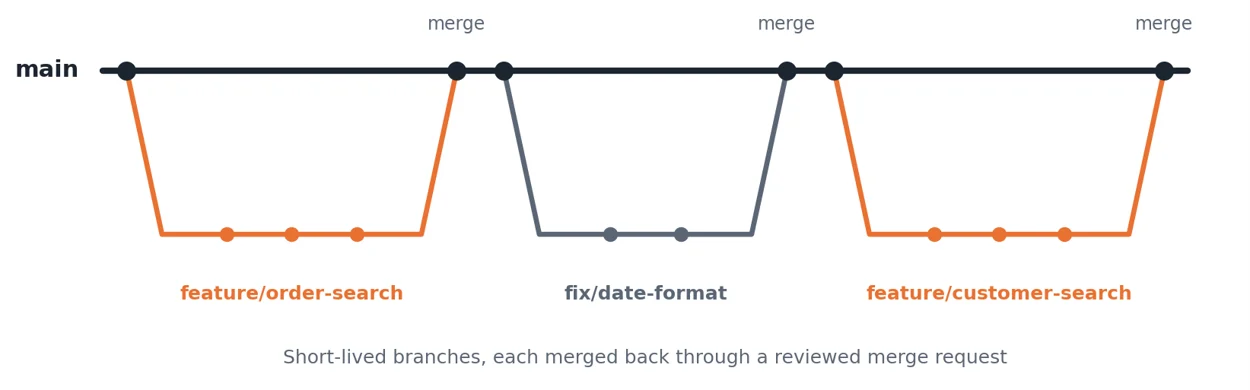
Visual Builder stores pages and flows as JSON and metadata files. When two people edit the same page on long-lived branches, merges become slow and error-prone. The remedy is simple: small branches, frequent merges and clear ownership. 

Make Git the backbone of your workflow

Figure 1. One task, one branch, one reviewed merge request. 

Branching rules 

  • Never build directly on main. Keep it stable and deployable at all times. 
  • One branch per task. A branch should map to one issue, whether a feature, a bug fix or a small refactor. 
  • Keep branches short-lived. Aim to merge within a few days. A branch open for weeks is a merge conflict waiting to happen. 
  • Bring main into your branch often. Do it at least once a day when others are merging, so conflicts stay small. 
  • Assign work by area. Divide tasks by flow, page or fragment so two people are rarely editing the same file. 

Branching rules

Figure 2. Short-lived branches merged back through reviewed merge requests. 

Write useful commit messages 

Commit history is the story of your application. A good message says what changed and why, in one line, and links to the issue when possible. 

Weak Better
update page Add status filter to order list (issue 142)
fixes Fix date format on invoice page for non-US locales
wip Extract customer summary into shared fragment

Run merge requests as real reviews 

Require at least one reviewer for every merge request. The reviewer should check more than whether the app runs. 

Review area Questions to ask
Readability Are names clear? Are action chains short and focused? Could a new team member follow the logic?
Reuse Is anything duplicated that should be a fragment, module or shared chain?
Data access Does the page request only the fields and rows it needs? Is paging or filtering done on the server?
Security Are secrets absent from the code? Is access enforced on the backend as well as in the UI?
Error handling What does the user see when a service call fails?
Traceability Is the merge request linked to an issue with a clear description?

Handle conflicts calmly 

  1. Bring the latest main into your branch before you start resolving anything. 
  2. Resolve conflicts one file at a time and keep both sides’ intent, not just one side’s text. 
  3. Open the app after resolving and click through the affected pages, because JSON that merges cleanly can still break bindings. 
  4. Ask the other author if you are unsure what their change was meant to do. 

4. Design applications for reuse and clarity 

Visual Builder makes it easy to build quickly and just as easy to build a mess. A little discipline early keeps the application maintainable as it grows. 

Design applications for reuse and clarity

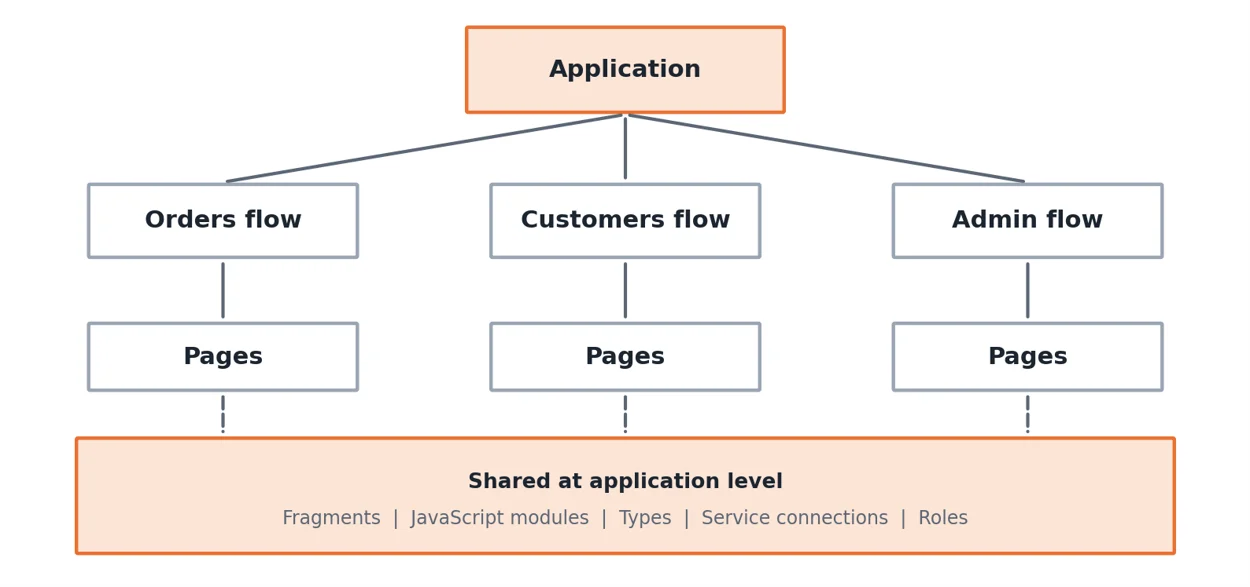
Figure 3. Flows group business areas. Anything used in more than one place moves to the shared layer. 

Use flows, pages and fragments deliberately 

  • Flows represent business areas, such as orders, customers and administration. Each flow has its own pages and can hold its own variables. 
  • Pages should stay focused on one task. If a page tries to do several things, split it. 
  • Fragments hold repeated UI, such as a customer summary card, a page header or a common filter bar. If you copy the same components onto a second page, that is the sign to create a fragment. 

Keep action chains small and clear 

  • Give each chain one job and a name that describes the outcome, for example loadOrders or saveCustomer. 
  • Break long chains into smaller ones that call each other. A chain with dozens of steps is hard to read, debug and review. 
  • Handle the failure path in every chain that calls a service. Show a clear message and stop cleanly. 
  • Use comments or descriptive labels on steps whose purpose is not obvious. 

Centralize shared logic 

Put validation rules, formatting helpers and common calculations in application-level JavaScript modules or shared chains instead of repeating them on each page. When a rule changes, you change it once. 

Scope variables carefully 

Scope Use it for Watch out for
Page Values only one page needs, such as a selected row or form field This is the default. Start here.
Flow Data shared by pages in the same business area Reset values when the user leaves the flow
Application Truly global data, such as the signed-in user or theme Too many become hidden global state that is hard to trace

Define types for your data 

Define types for records and service responses so components, variables and service calls agree on shape. It prevents subtle binding errors and makes pages easier to understand. 

Design for clarity in the interface 

  • Use plain words that users recognize, and keep action names consistent across the app, such as always using Save and Cancel. 
  • Show loading and empty states. A blank area looks like a bug. 
  • Keep pages light. Move rarely used content to separate pages or load it on demand. 

5. Manage service connections properly 

Most real applications sit on top of REST services, whether Oracle Fusion applications, ORDS, or custom APIs. How you connect to them affects security, speed and how easily you can move between environments. 

Do Avoid
Define each connection once and reuse it across pages Hard-coding endpoints inside individual calls
Configure endpoints and credentials per environment Editing URLs by hand before each release
Request only the fields you need Fetching whole records when a page shows three columns
Filter, sort and paginate on the server Loading thousands of rows to filter in the browser
Show a clear message and log details when a call fails Leaving the user with a blank screen
Agree with service owners on versions and changes Discovering breaking changes in production

Common slowdown

Pulling large collections into the browser and filtering there is one of the most common causes of slow applications. Push filtering, sorting and paging to the service, and measure with realistic data volumes.

6. Build security in from day one 

Security added at the end is expensive and incomplete. Treat it as part of the design of every page and every integration. 

Practice Why it matters Avoid
Enforce permissions on the backend service Hidden UI can be bypassed. Server checks cannot. Treating hidden buttons as security
Restrict flows and pages with roles Users see only what they should Giving everyone access to every page
Use credential and secret features Keeps secrets out of source control Committing passwords, tokens or API keys
Validate input on client and server Client checks help users, server checks protect data Trusting client-side validation alone
Review who can deploy to production Limits accidental or unauthorized changes Open access to production pipelines

Also review access regularly. People change teams, and permissions granted for a project often outlive the need for them. 

7. Automate delivery with environments and pipelines 

The DevOps side of VBS is where teams gain the most reliability. Manual deployments depend on one person’s memory. Pipelines turn the process into something anyone can run and everyone can trust. 

Automate delivery with environments and pipelines

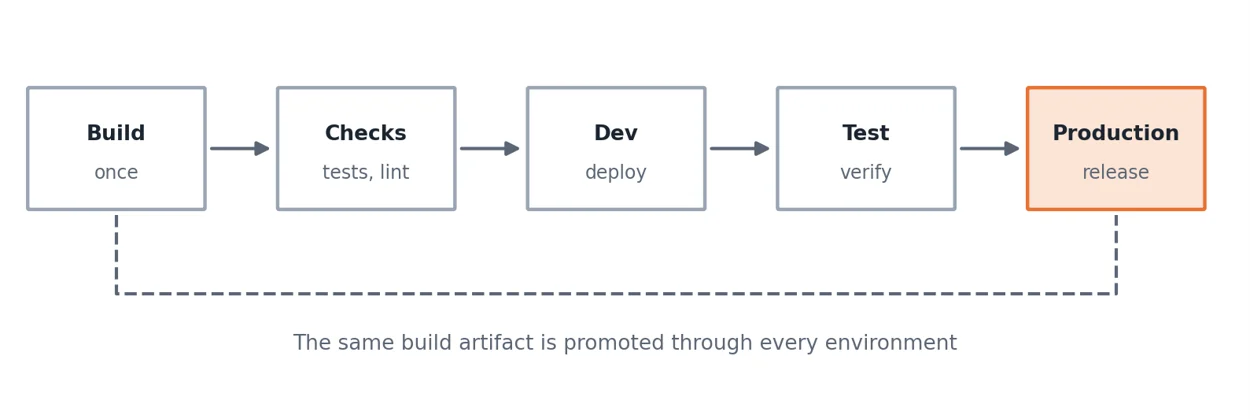
Figure 4. Build once, run checks, then promote the same artifact through each environment. 

Use separate environments 

Environment Purpose Typical users
Development Try changes quickly and break things safely Developers
Test Verify features and regressions with realistic data Testers, reviewers, product owners
Production Serve real users End users

Design the pipeline in stages 

Stage What happens Fails the run when
Build Package the application once The build cannot complete
Checks Run automated tests and code quality checks Any required check fails
Deploy to dev Publish to the development environment Deployment errors occur
Deploy to test Publish the same artifact for verification Smoke tests fail
Deploy to production Release with approval Approval is withheld or a health check fails

Release practices that reduce risk 

  • Promote the same artifact. Build once and promote that artifact so what you tested is exactly what you release. 
  • Gate merges on pipeline results. A broken main slows the whole team, so require a passing build before merging. 
  • Require approval for production. A quick sign-off from a second person catches many mistakes. 
  • Keep a rollback plan. Know how to return to the previous version before you need to. 
  • Release small and often. Small releases are easier to test and easier to undo. 
  • Keep deployment repeatable. Anyone on the team should be able to trigger it and get the same result. 

8. Test and watch performance 

Type What to check When
Manual walkthrough Key user journeys from start to finish, including error cases Before every release
Automated UI or API tests The most important paths, run repeatedly with the same result In the pipeline on every change
Cross-browser and device checks Layout and behavior on supported browsers and screen sizes Before release and after major UI changes
Performance checks Page load, service response times and behavior with realistic data volumes Regularly, and whenever data grows
Access checks That each role sees only the pages and data intended When roles or pages change

Performance habits 

  • Watch the browser console and network tab while developing. Errors, failed calls and slow requests show up there first. 
  • Use pagination and lazy loading for large lists. 
  • Avoid calling the same service several times on one page when one call would do. 
  • Test with production-sized data, not just a handful of sample records. 
  • Remove unused pages, variables and connections regularly. Dead code confuses newcomers and hides real problems. 

9. Track work and document as you go 

Use issues and boards 

Every task and bug should exist as an issue, linked to its branch and merge request. That gives you a history of what changed and why and lets the team see progress on the board without status meetings. 

A useful issue contains 

  • A short outcome statement, such as: Users can filter orders by status. 
  • Acceptance criteria that can be checked. 
  • Any linked designs, service details or dependencies. 

Agree on a definition of done 

A task is done when…
The change is merged through a reviewed merge request linked to its issue
The pipeline has passed, including automated checks
It has been verified in the test environment
Any new service connection, role or setting is documented
The README or release notes reflect the change

Keep a README for every application 

Section Contents
Purpose What the app does and who uses it
Structure Main flows, shared fragments and modules
Connections Services used and who owns them
Environments What differs between development, test and production
Deployment How to release and how to roll back
Contacts Who to ask about the app, its services and its data

Ten minutes of writing saves hours of onboarding. 

10. Common mistakes and how to fix them 

Mistake Effect Fix
Building directly on main Unreviewed changes and broken releases Branch per task and require merge requests
Long-lived branches Large, painful merges Merge within days and sync often
Copying components between pages Fixes must be repeated everywhere Create fragments and shared modules
Very long action chains Hard to debug or review Split into small, named chains
Too many application-level variables Hidden state and unexpected behavior Use the narrowest scope that works
Hard-coded endpoints and credentials Risky releases and leaked secrets Configure per environment and use secret features
Filtering in the browser Slow pages with large data Filter and paginate on the server
Rebuilding for each environment Untested code reaches production Promote one artifact through all environments
Skipping documentation Knowledge lives in one person’s head Keep a README and definition of done

Final thoughts 

The theme running through all of this is that fast tools reward steady habits. Visual Builder Studio speeds up development, but version control discipline, modular design, secure and efficient integrations and automated delivery decide whether a project stays healthy as it grows. Start with a few practices, make them routine and add more as the team gains confidence. Done well, your team can move quickly without breaking things. 

Why Are You Still Paying Invoices Twice in Oracle Fusion?

A single supplier invoice paid twice on a multi-million-dollar AP run rarely looks dramatic on its own. Scale that pattern across a few dozen vendors, a handful of maverick channels, and one busy close cycle, and you are staring at six-figure leakage that never appears as a clean line item on the board pack. 

Duplicate invoice payments usually come from fragmented visibility inside live Oracle Fusion deployments. When you treat spend management as a measurable outcome discipline rather than another software layer, finance teams can catch the same bill before it clears twice and turn that leakage into documented savings. 

You already run Oracle Fusion Applications. The data sits there. Yet the same supplier invoice still slips through multiple times because no single governed view connects request, receipt, and payment across every channel. The result shows up in your DPO numbers, audit findings, and the hours your team spends chasing corrections instead of closing the books. 

This article walks through the full spend lifecycle, the root causes that create duplicate payments, the real cost to the business, and the practical steps you can take inside your existing system. The goal is simple: turn hidden leakage into tracked value you can defend at the board. 

What spend management actually covers?

Spend management governs the entire request-to-pay lifecycle. It starts with intake and ends with post-payment analysis. Expense tracking only records what employees already spent and then reimburses them. Procurement systems often stay in their own silo. The gap between those two leaves room for the same invoice to be approved and paid more than once. 

Think of it this way. Expense tracking is the receipt drawer. Spend management is the full kitchen: who ordered, what was approved, what arrived, what was billed, what was paid, and whether any of those steps repeated by accident. If you only watch the drawer, you will never see the second payment leave the account. 

The full process runs from initial request through sourcing, ordering, receiving, invoicing, payment, and ongoing analysis. Oracle Fusion already captures much of this data across Payables, Procurement, Receiving, and related modules. The issue is not missing information. It is the lack of a single, governed flow that flags duplicates before money leaves the account. 

Gartner’s definition of spend analytics solutions centers on cleansing, normalizing, enriching, and visualizing spend data so teams can see spend outside standard processes and spot savings opportunities. That framing matches what Oracle Fusion customers already hold in the system: the raw transactions exist, but without a disciplined view they do not protect you from paying twice. 

Three categories of spend matter for duplicate risk: 

  • Direct spend: materials and services tied to core delivery, usually under stronger PO and receipt controls 
  • Indirect spend: facilities, professional services, software, travel-adjacent costs, and other operating purchases that often bypass tight matching 
  • Maverick spend: purchases that skip preferred suppliers, contracts, or approval paths entirely 

Indirect spend and maverick purchases hide the most duplicates because they bypass standard controls. When a manager approves an invoice outside the central process, the system has no reliable record of the prior payment. A supplier resubmits a slightly altered invoice number. A shared-services clerk keys the same bill into two business units. Visibility gaps create the exact conditions that let one invoice become two payments. 

So what should you demand from spend management inside Oracle Fusion? Not a new dashboard for its own sake. A governed lifecycle that answers, for every dollar leaving the company: who requested it, what policy applied, what was received, whether the invoice already exists, and whether payment should stop. 

Why duplicate payments keep happening in Oracle environments 

Duplicate payments rarely start with fraud. They start with incomplete sightlines. Finance leaders often cannot see every channel where a supplier can submit, resubmit, or re-route a bill. Without that view, duplicate checks fail at the exact moment they matter: before the payment batch runs. 

Maverick spend and manual approval bottlenecks make the problem worse. When approvals route through email, chat threads, or spreadsheets, the three-way match never happens in real time. A PO exists in one module. A receipt sits in another. The invoice arrives through a shared mailbox. Nobody owns the cross-check, so the same amount clears twice under slightly different references. 

Ineffective configuration is another common driver. Post-go-live Oracle Fusion setups often remain tuned for transaction recording rather than duplicate prevention. Matching rules stay loose so the business can “keep moving.” Supplier master data carries duplicates or near-duplicates. Invoice holds fire too late, or not at all, when amount, date, and supplier patterns should have stopped the run. 

Pre-approved manager verification processes add another layer of risk. A manager signs off on an invoice that already cleared weeks earlier because the system never cross-checked the supplier, amount, and date against prior payments. The human step feels like control. In practice it becomes a rubber stamp when the person approving has no clean list of what already paid. 

Sounds familiar? Many Oracle Fusion programs hit this pattern six to eighteen months after go-live. The implementation team optimized for cutover. Controls that would catch duplicates were deferred. Workarounds became permanent. Shared services inherited a process that records spend well and governs it poorly. 

The root condition is structural: 

  1. Multiple intake paths for the same supplier bill 
  2. Incomplete or inconsistent supplier and invoice identifiers 
  3. Matching rules that prioritize speed over first-time accuracy 
  4. Approvals disconnected from prior-payment history 
  5. No owner for Spend Leakage Control as a board-level KPI 

Fix the structure and the duplicates drop. Add another disconnected tool on top of the same structure and they usually do not. 

The real cost of paying invoices twice 

The cost of a duplicate payment is larger than the second check. You lose the cash twice, then you lose the life-hours spent finding it, recovering it, explaining it to audit, and rebuilding trust with the supplier who may already have applied the extra funds to a different open item. 

Translate that into Oracle Fusion-relevant KPIs and the board conversation changes. Weak first-time match rates stretch exception queues and slow Close Cycle Reduction. DSO/DPO Optimization suffers when AP is buried in cleanup instead of optimizing working capital deliberately. Audit Readiness erodes when samples keep surfacing the same control failure. Supplier Performance Index scores get noisy because billing disputes mix real performance issues with your own process gaps. 

Consider a simple internal baseline exercise. Pull a recent quarter of paid invoices. Flag exact and near matches on supplier, amount, date window, and PO reference. Even a modest duplicate rate compounds fast across high-volume categories: facilities, contingent labor, logistics surcharges, marketing services, and recurring software invoices. The leakage rarely sits in one dramatic fraud case. It sits in dozens of “small” repeats that nobody owned. 

There is also opportunity cost. Every hour your AP and procurement teams spend reconciling double payments is an hour not spent on Strategic Spend Control, contract compliance, or supplier consolidation. That is the life-hours problem in miniature. Money left the company. Time left with it. Neither shows up cleanly as “duplicate invoice line” on the P&L. 

Senior leaders already feel pressure on corporate spending levels. When the story you bring them is only “we need another module,” the conversation stalls. When the story is “here is our current leakage baseline, here is the first-time match gap, and here is the recoverable value inside Oracle Fusion,” you get airtime. The cost becomes a measurable outcome problem, not a vague process complaint. 

Frame the damage in three layers when you brief the CFO or COO: 

  • Cash leakage: amounts paid more than once, net of recoveries 
  • Process leakage: exception volume, rework hours, and delayed close tasks 
  • Control leakage: audit findings, weak evidence packs, and eroded confidence in AP controls 

High-performing finance teams treat those three as one program. Average teams chase each invoice as a one-off. The difference is not heroics. It is whether spend management is measured like any other operational outcome. 

How effective spend management stops the leakage 

You do not need a new stack to start. You need a sequence. The Business Value Maximization (BVM) model applies four S.E.E.R. phases to spend control: Sense, Evaluate, Execute, and Retrospect. 

In the Sense phase you map every payment channel inside Oracle Fusion and adjacent intake paths. Where can an invoice enter? Which business units bypass central AP? Which suppliers bill multiple legal entities? Which manual journals still touch payables? The output is a plain map of exposure, not a wish list of tools. 

In Evaluate you baseline current duplicate rates, first-time match performance, maverick spend share, and exception aging. Pick a sample window. Document the rules you used so the baseline is defensible. This is where Spend Leakage Control stops being a slogan and becomes a number you can move. 

Execute brings centralised data discipline and automated three-way matching that catches duplicates before payment. Tighten supplier master hygiene. Align invoice matching rules with real risk, not only with historical “keep the queue moving” habits. Route exceptions to owners who can stop a payment, not only comment on it. Supplier performance indexing flags vendors with repeated billing issues. Contract compliance checks reduce off-contract purchases that bypass controls. 

Retrospect measures recovered value against the original baseline. What duplicate rate did you start with? What is it now? How many life-hours left the exception queue? Which controls still fail under volume? That feedback loop is what turns a cleanup project into an operating rhythm. 

Quick wins often sit inside modules you already own: 

  • Enforce consistent supplier identifiers and block obvious master duplicates 
  • Strengthen three-way match thresholds on high-risk categories first 
  • Require PO references on categories where maverick volume is highest 
  • Surface prior-payment warnings in the approval path managers actually use 
  • Report first-time match rate weekly during the first ninety days of the program 

The largest gains still come from process discipline, not from adding another tool. Business Value Maximization (BVM) shows how to sequence these changes so each step produces measurable outcome data. For teams already live on Fusion and stuck in post-go-live drift, Oracle Fusion process optimization work is often the practical path to re-tune matching, approvals, and ownership without a second implementation circus. 

Ask one hard question before you buy anything new: if we fixed master data, matching, and ownership inside Oracle Fusion this quarter, what percentage of our duplicate problem would still remain? If the honest answer is “most of it would shrink,” start there. 

Common misconceptions that keep the problem alive 

Many teams assume more software will close visibility gaps. The data already lives in Oracle Fusion. The missing piece is governed process, not another layer that creates a second version of the truth. Software can help when process owners are clear. It cannot replace them. 

Others treat indirect spend as too small to matter. Indirect and maverick categories together often rival direct spend in volume and carry the highest duplicate risk precisely because controls are looser. The “small” marketing invoice and the “routine” facilities bill are where repeats hide. 

A third misconception holds that existing ERP data is already clean enough for duplicate detection. Post-go-live configurations frequently leave fields incomplete, inconsistently used, or optional in the wrong places. If invoice number formats vary by business unit, if supplier sites multiply without reason, if receipt data is skipped under pressure, your duplicate logic is guessing. 

Finally, some view spend management as a procurement-only task. Finance owns the cash. Procurement owns the supplier relationship. Operations owns the receipt. Shared services owns the queue. If only one of those groups “owns spend,” the invoice still has three other doors to walk through. The outcome discipline must span all of them. 

There is also a commercial misconception worth naming. Traditional time-and-materials consulting can document the problem for months without tying fees to leakage recovered or match rates improved. Outcome-based consulting differs because payment ties to verified results rather than hours logged. That alignment changes what the engagement optimizes for: board-visible KPIs, not slideware. 

If you think that sounds like a process lecture dressed up as strategy, try this frame-flip from quality control on a factory line. Inspectors at the end of the line find defects. Designers who change the line prevent them. Most Oracle Fusion teams are still hiring more inspectors for AP exceptions. Spend management that works redesigns the line: intake, match, approve, pay. 

Clear the misconceptions and the work gets simpler. Keep them and you will keep paying the same invoices twice while debating tool shortlists. 

How to measure whether your spend management is working 

If you cannot measure it inside Oracle Fusion, you do not control it. Start with persona-specific metrics that already map to how executives defend performance. 

CFO-facing metrics 

  • Close Cycle Reduction 
  • DSO/DPO Optimization 
  • Spend Leakage Control 
  • Audit Readiness 
  • Period Close Optimization 

CPO / CSCO / COO-facing metrics 

  • Strategic Spend Control 
  • Supplier Performance Index 
  • Optimized Inventory Turns (where receipt quality affects match rates) 
  • Improved Backordered Rate (where incomplete receipts drive invoice noise) 

Leading indicators for the whole program 

  • First-time invoice match rate 
  • Maverick spend percentage 
  • Duplicate payment rate (exact and near match) 
  • Exception aging and rework hours 
  • Percent of spend on contract 

Baseline before you change anything. Choose a recent, representative period. Define duplicate logic in writing (same supplier, amount tolerance, date window, PO or invoice reference rules). Run the sample. Record the rate and the cash at risk. That baseline is your before picture for Value Demonstration later. 

Then set a short measurement cadence. Weekly first-time match and exception aging during stabilization. Monthly Spend Leakage Control and maverick share for the steering group. Quarterly Audit Readiness evidence packs so you are not inventing a story the week before external audit arrives. 

Connect the numbers to the Value Demonstration phase of Business Value Maximization. The point is not a prettier report. The point is proving that process changes moved a KPI the board already understands. If first-time match rises and duplicate rate falls while close tasks shrink, you have a value story. If dashboards multiply and the KPIs do not move, you have theatre. 

A practical starter checklist: 

  1. Agree owners for each KPI (finance, procurement, shared services) 
  2. Freeze baseline definitions for ninety days so trends are comparable 
  3. Instrument Oracle Fusion reports or OTBI analyses you can rerun without heroics 
  4. Review one high-risk category end-to-end each month (request through payment) 
  5. Retire workarounds that bypass the controls you just measured 

If you are still unsure where your configuration and process maturity sit, pair this measurement plan with a structured self-assessment and a clear modernize path for ERP value realization. Measurement without ownership is just another report. Ownership without measurement is opinion. 

Conclusion 

Duplicate invoice payments are a visibility and process problem that Oracle Fusion customers can turn into measurable savings by applying disciplined spend management inside their existing system. The data is already there. The next step is governed flow, clear ownership, and outcome tracking against KPIs the board already watches. 

Start with a baseline, tighten the match, and measure what changes. If you want a deeper KPI and framework pack for that work, download the Tiny Transformations e-book. For ongoing post-go-live support patterns that keep controls from drifting, explore Oracle Fusion support and managed services. Then book a strategy session to map your current leakage against the same outcome measures and decide what to fix first. 

When Planners Override Oracle Forecasts, Who Measures the Value Lost?

One planner override on one high-volume SKU can push an extra $180,000 of safety stock into the warehouse. Nobody notices, because nobody checks whether the override beat the forecast it replaced. 

The short answer: manufacturers improve demand planning and inventory visibility in Oracle Fusion by measuring Forecast Value Add, the accuracy each override adds to, or takes from, the statistical baseline. Freeze the baseline, capture the final plan, score both against actual demand. Overrides then stop quietly inflating safety stock, and Optimized Inventory Turns rise while service holds. 

That is the number that turns an override from a habit into a decision. Below: what it is, how you calculate it from data your Oracle Fusion deployment already records, and where a planner sees it and acts on it. 

What is Forecast Value Add? 

Forecast Value Add is the accuracy you gain, or lose, when a planner changes the statistical forecast. 

Two forecasts exist for every item, every cycle. The first is the statistical baseline Oracle Fusion produces. The second is the final plan after human edits. Actual demand arrives later and settles the argument. 

If the final plan landed closer to actual demand than the baseline did, the override added accuracy. If it landed further away, the override added error. Positive value add, an earned exception. Negative value add, an expensive guess. 

That is the whole idea, and it is not a stick to beat planners with. Oracle Demand Management expects planners to adjust the statistical forecast when they hold business intelligence the model cannot see, and often the planner is right. The problem is that most teams never find out which overrides were the right ones. 

So the metric does not ban overrides. It prices them. (And prices, unlike opinions, end meetings.) 

How do you work it out from Oracle Fusion data? 

Four steps, all of them running on data your deployment already records. 

  1. Freeze the baseline. Snapshot the statistical forecast before any human edit, at item and horizon level. If the baseline can drift mid-cycle, nothing downstream is comparable. 
  2. Capture the final plan. Record the consensus forecast that actually released into supply, and who changed it. 
  3. Score both against actuals. When demand lands, measure the error on each forecast using one agreed metric: MAPE or WAPE, whichever your team already argues about. 
  4. Take the difference. Baseline error minus final-plan error is the value add for that item and cycle. Roll it up by planner, by item segment, by horizon. 

Three companion measures make the number readable. Override rate tells you how often the baseline gets touched. Bias tells you whether overrides lean systematically high or low. Accuracy before and after tells you the size of the swing. 

Tie that back to the SKU in the opening. The override that pushed $180,000 into safety stock shows up here as a single row: low baseline error, higher final-plan error, negative value add, one planner, one horizon. Nothing about that row is an accusation. It is simply the first time the cost of that one edit was visible to anybody. 

One caveat worth saying plainly: none of this arrives as a finished Fusion report. The transactions and the forecast versions sit in your Oracle Fusion data. The snapshot discipline, the comparison, and the scorecard are work your planning team or your partner builds on top of that data. 

Where does a planner actually see it? 

A metric nobody opens is wallpaper. Forecast Value Add has to land in three places. 

On a weekly scorecard. Override rate, net value add, and the five items contributing the most absolute error. One page, published to the planning team, not parked in a folder only the centre of excellence can open. 

In the exception list. Set a tolerance band. Overrides on A items that fall outside it get reviewed. A one-unit tweak on a C item does not. Visibility, not bureaucracy. 

In the S&OP meeting, as the opening question. Not “what is the number?”, which invites negotiation. “What was the value add of last cycle’s overrides?”, which invites evidence. Planners who added accuracy explain their method. A pattern of negative value add triggers a look at the inputs, not at the person. 

Then keep the reason attached to the record. Require a short coded reason on material overrides (promotion, customer intelligence, supply constraint, one-off event) in Oracle’s planner notes, not in somebody’s inbox. When a promotion override keeps adding value, that signal belongs in your governed inputs rather than in a heroic edit five minutes before the freeze. 

Expect friction for two or three cycles. People who used to win arguments with volume have to start winning them with evidence. 

Why do planners override in the first place? 

Because the process, not the planner, made overriding the rational move. Three conditions do most of the damage. 

The baseline is opaque. The statistical number arrives finished, with no easy way to trace which shipment history or which promotion flag moved it. People trust what they can inspect, and a black box invites a private rewrite. 

Demand intelligence has no front door. Sales, marketing and finance each hold a slice: pipeline shifts, campaign timing, pricing moves, channel mix. With no structured handoff into Oracle Demand Management, that slice stays a hallway conversation and ends as a spreadsheet edit. 

And re-keying is tiring. The more swivel-chair work a planner does, the more likely the plan finishes in Excel (which is where silent overrides are born). Inside an Orbrick engagement, Smart.Assist cuts data entry time by 50 percent, so planner hours go to judgment instead of retyping figures Oracle Fusion already recorded. 

Close those three and the fourth fix comes free. Cleaner, segmented history produces better baselines. Better baselines need fewer overrides. The overrides that survive are the ones that genuinely deserve a human. Not sure which of the three is biting you? An honest read of your own ERP maturity is a seven-minute way to find out. 

How does this reach Optimized Inventory Turns? 

CSCOs do not fund forecast science for its own sake. They fund it because the demand signal sets the inventory posture. 

Safety stock responds to forecast error and bias. When overrides stop injecting error nobody measured, the error band tightens, and the buffer that existed to cover planner disagreement can come down without touching fill rate. 

Order release settles too. Supply planners stop launching early just in case, and stop expediting late when the consensus number whipsaws. Premium freight and hot lists are the shadow P&L of unmeasured overrides. 

The KPI that captures all of it is Optimized Inventory Turns. Excess finished goods and raw buffers release while service holds, so turns rise because the same demand is planned with less protective inventory, not because you starved the network. Working capital follows, and finance reads it in inventory days and cash conversion. 

Business Value Maximization is how we carry a planning metric through to that board metric instead of stopping at “the forecast looks better”. Sense the override gap, evaluate which segments are costing you turns, execute the instrumentation, then retrospect on turns and cash. Teams that want the weekly cycle to hold after the first rebuild usually pair it with structured Oracle Fusion support. 

Conclusion 

Run the test yourself this month. Pull override rate and Forecast Value Add for your top revenue segments, then pull safety stock and turns for the same slices. High override rate, flat value add, fat buffers: that is your post-go-live value leak, and a measured baseline is the cheapest tool you have to close it. 

Download the free Tiny Transformations e-book for the KPI frameworks supply chain leaders use to keep planning metrics tied to turns and cash. Then schedule a strategy session to map the same discipline onto your live Oracle deployment. 

The Invoice Is Only Half the Story: What Oracle’s Payables and Payments Agents Actually Change

A supplier agrees to 2/10 net 60. In simple terms, you get a 2% discount if you pay within 10 days. If you don’t, you pay the full amount within 60 days.

Now imagine the invoice comes into AP, but the payment terms are captured as Net 30. Maybe the invoice was read incorrectly. Maybe an old default was picked up. Maybe someone entered the terms manually. Nothing looks obviously wrong. The invoice gets approved, goes into the next payment run, and the company pays on day 30.

The invoice was paid. The accounting is correct. No error message appeared. But the company still lost the 2% discount, and it paid 30 days before it had to.

That’s the part of AP automation that often gets missed: a mistake at the beginning of the process can affect a decision much later. That is why I think Oracle’s Payables Agent and Payments Agent are worth looking at together. Most conversations about AP automation start and end with invoice capture, but what happens to that information afterwards matters just as much.

Before the agents: How AP usually worked

On many Fusion projects, AP has looked similar. Invoices arrive in a shared mailbox, some suppliers use the supplier portal, and others send scanned copies through different departments. Then someone has to open each invoice, enter the details, find the PO, check the supplier, fix missing information and deal with exceptions. Meanwhile, payment runs happen on a fixed schedule, often because that is how the process has always been run.

It’s not a user problem. There are simply too many small manual steps, and that is where the new agents start to change things.

Starting at the inbox

The Payables Agent starts with invoice intake. Oracle’s Capture setup lets you define where invoices come from and how they’re grouped into streams. A stream is a flow of documents with something in common, such as the sender, file type or channel. If you run multiple business units, you can also map an email alias to a business unit so invoices that don’t match anything else still land in the right place. From there, Document IO reads each document and maps it into invoice fields, across file types, page counts and languages.

Training has also changed a lot since 26B, when Document IO replaced the older Intelligent Document Recognition. Because it uses large language models, most invoice attributes are picked up automatically, and you only train the few fields it misses. That is usually a one-time job per invoice layout, so start with high-volume suppliers and the ones with messy layouts. For example, complex invoices from suppliers such as Amazon may need additional training when certain fields aren’t being captured correctly. Their layouts didn’t follow a standard format, and some fields weren’t being picked up correctly. Once the training was saved, the agent recognized those fields on every new invoice from the same suppliers, so nobody had to correct them again.

26C went further and added training for descriptive and global descriptive flexfields on PDF and image invoices. That is useful if your company tracks its own invoice attributes or has country-specific fields to capture.

Most teams train in a test environment first, so moving that learning to production is always a question. In 26D you can export and import fingerprint-based training yourself. The import checks the file and warns you before it overwrites existing learning. Read those warnings properly, especially if production already has newer training than test, or you could replace good learning with old test data.

From setup screens to business policies

Instead of building every rule manually through setup screens, Compliance and Control lets you upload business policy documents, and the agent reads them and turns them into rules. Completion policies fill in what’s missing from the invoice, like account combinations, tax determinants and project information. Control policies check invoices against your criteria and against related POs or receipts and flag anything that doesn’t fit for review.

This needs a bit more care than it looks. Some fields can only be filled in when specific criteria are present. A rule that fills in the distribution account, for example, needs Ledger as one of its criteria fields. Leave it out and the rule never matches, so invoices keep coming through with the account blank. It’s an easy one to miss, and it comes up often in real implementations and in community discussions.

26D also moves invoice matching controls into Compliance and Control. Until now, one tolerance at the supplier site or business unit had to cover everything. Say that tolerance is 2%, but medical consumable prices regularly move up to 5%. Every one of those invoices goes on a price hold, and someone releases it without changing anything. With matching controls, you can add a rule for that business unit and purchasing category with a 5% tolerance. An invoice 4% over the PO price gets its hold released automatically. One that is 7% over still waits for review. Your existing tolerances stay in place as the baseline.

What happens when an invoice needs attention

Not every invoice goes straight through, and that is fine. The Streams page tells you quickly whether the problem is with the whole file or just one invoice buried inside it, which matters more than it sounds. I’ve seen teams waste time investigating a “failed” file when only one line item out of twenty had an issue.

The Payables home page helps here too. Instead of opening five screens and filtering each one, you get a prioritized list to start from. And when a document pauses for review, that is not a failure. It’s a control point doing its job, so there’s no need to panic when you see one.

The Invoice List feels more like a conversation than a search form. You ask for what you need in plain language, then act on it directly, whether that is releasing an exception, correcting a value or overriding an anomaly. If an import gets rejected, the correction spreadsheet is still there as a fallback, which is reassuring if you’re used to the old way of working.

The supplier master still matters

AI can read an invoice, but it can only match what your supplier master tells it. The invoice says ABC Trading Ltd, the supplier master says ABC Trading Limited. Or the invoice comes from a different legal entity or email address. Each small difference can create an exception someone has to investigate, and across thousands of invoices that becomes a real workload.

The bigger risk is a wrong match with no exception at all. Payables Agent identifies suppliers using details like name, address and tax registration number. If two suppliers share the same address, an invoice from one could be matched to the other. If no one catches it during review, the payment goes to the wrong supplier’s bank account. Caught before payment, it’s a quick fix. Caught after, someone must chase a refund from the other supplier, reverse the payment and pay the right one again.

Finding the right suppliers for discounts

The Payments Agent also helps you figure out which suppliers are worth approaching for early payment discounts, rather than guessing. You can sort suppliers by how much you spend with them, then narrow that list by things like their payment terms, how often they’ve taken a discount before, how often they’ve missed one, and whether they’ve said yes to an early-payment offer in the past. Once you’ve picked a supplier, the Supplier Offers Assistant drafts the offer, sends it, and keeps track of whether they accept.

On the payment execution side, you can just ask in plain language how a payment file is doing, or why something got rejected. It also flags things worth checking on its own, like a payment that hasn’t reconciled, a card payment that keeps failing, an offer that’s about to expire, or a supplier whose offer email is missing so the offer can’t even go out.

One invoice, end to end

Put together, the two agents make more sense as one AP story.

What Oracle Payables and Payments Agents Actually Change

Controls, approvals and user review stay important across the whole process. People remain in the flow. The system just does more of the routine work before they need to step in.

What needs to be ready before you start

The agents get most of the attention, but the setup underneath them decides how well they work.

  • Supplier and PO data. Names, addresses and PO information should match what appears on invoices. The supplier profile matters on the payment side too: if the offer email address is missing, the system can’t send the offer.
  • Clear business policies. The agent builds rules from your policies, so a vague or conflicting policy produces rules that need more review. Treat generated policies as something to validate, not switch on blindly.
  • Business unit access. A user may reach the Streams page but still be unable to see invoice details if the BU data security isn’t in place. After granting BU access to the custom job role, run Process Permission Group Policies.
  • The Payables Agent has its own duties for document processing, capture, policy configuration, invoice processing and insights. For the Payments Agent, Oracle’s documented setup uses a custom role based on Payment Specialist, with the required permission groups and the AI agent runtime duty.
  • Your actual payment program terms. If you’ve negotiated specific dynamic discounting or virtual card terms, those documents need to be given to the agent. In AI Agent Studio, upload the financing program documents through the Financing Programs tool, then run Process Agent Documents. Otherwise, the assistant may use system defaults, and the benefit calculations won’t reflect your negotiated terms.

One thing I’ve learned from Fusion projects is that the problem isn’t always where you expect it. A user logs in, the menu is there, the page opens, but there’s no data. It looks like a functional defect. Very often it’s a role or data-access issue. I’ve lost more testing time to these than to some genuine functional defects, so I check roles and data access early, before the testing team reports that something is missing.

The agents don’t replace your controls

None of this replaces your existing controls, and that’s by design. Every recommendation and draft still needs a human to review it, and your approvals, segregation of duties and validations keep working exactly as before. Payment scheduling still uses your existing Payment process request templates and still needs someone to confirm it before it goes out, which matters a lot since real money is moving. The same caution applies to supplier offers. A supplier can qualify for a discounting program on paper and still say no. And since the traditional Fusion pages stay available right alongside the agents, a controlled rollout with a small group of high-volume suppliers makes far more sense than switching everything on at once.

Closing the loop at month end

In 26D, Oracle introduced the Payables Period Close Workspace, an agentic application for the usual month-end hunt across five different screens. For the selected ledger and period, it pulls invoices, payments and period status into one place, ranks priority actions by urgency and monetary impact, and lets you use Ask Oracle to see what each issue is holding up. It also follows your own SOP. Your milestones, thresholds, owners and signoffs decide what counts as done, what needs confirmation and what gets escalated.

Fusion Claw, recently announced by Oracle, pushes this further. It’s a runtime that lets Fusion agentic applications actually carry out work, within your SOPs, policies and approval limits, at whatever level of autonomy you choose. Every action leaves an Outcome Receipt showing the authority used, the evidence and the result.

Which brings me back to that Net 30 invoice. It doesn’t go away once it’s paid. If nobody catches it, it turns up again at month end as something blocking the close. As these applications get more autonomy, that matters even more, because an agent is only as reliable as the data it acts on.

Where I would start

If I were starting an implementation today, I wouldn’t start with the most impressive AI feature. I’d start with the basics: clean supplier data, sensible invoice streams, the right document formats and training, clear business policies, and correct roles and BU access. Once those are in place, I’d bring the Payments Agent in.

If the supplier, amount, payment terms or dates are wrong, automation at the payment end won’t fix it. It will just make the wrong decision faster. For me, that’s what matters most with these new AP agents: keeping the information reliable all the way from capture to payment.

From AI That Answers to AI That Acts

Understanding the Tool Calling Pattern in Oracle AI Agent Studio

An AI agent can understand a purchase-order question perfectly. But what happens when the answer is sitting inside Oracle Fusion, and the model does not have that information yet?

That is where tool calling becomes important.

An LLM is good at understanding language, reasoning over context, and generating responses. What it does not automatically have is access to every live business system an organization uses. If a manager asks, “Which purchase orders are delayed and why?”, the model needs a controlled way to reach the system that actually contains the purchase-order information.

A tool provides that bridge. It gives the agent a defined capability, such as retrieving a purchase order, checking inventory, querying business data, calling an external REST API, retrieving information, or performing an approved operation.

The distinction is worth keeping simple: the tool is the capability; tool calling is the agent deciding to use that capability as part of completing a larger task.

What happens when the agent needs a tool?

Consider a manager asking:

“Show me delayed purchase orders and check whether inventory is causing the delay.”

The agent first interprets the request using the model, its instructions, the relevant topic, and the capabilities available to it. The first part of the request may require current purchase-order information, so the agent can select an appropriate configured tool and provide the required parameters.

The connected system processes the request and returns structured information. The agent then looks at that result and determines what is still needed. If the purchase order points to a particular item or organization, the agent may need inventory information next. It can make another tool call using the relevant information from the first result.

The inventory result then becomes part of the context used to answer the original question. The user asked one question, but the agent may have needed several tool calls to complete it.

This is the core of the Tool Calling Pattern: instead of trying to generate every part of an answer from its existing knowledge, the agent can obtain current information or perform a defined operation through an available capability.

A tool needs a clear contract

This is where tool design starts to matter. A tool is not simply an API endpoint with a name attached to it. The agent needs enough information to understand what the tool does, when it is appropriate, which inputs it expects, and what sort of result it returns.

For example, a tool called GetInventory does not tell the agent very much by itself. A description such as “Returns the available quantity of an item for a specified inventory organization” gives the agent a much clearer idea of the capability.

Technically, a tool can be treated as a contract between the agent and the underlying capability. That contract includes the operation, input parameters, connection or authentication requirements, and expected result.

Suppose the tool requires an item ID and an organization ID. If the agent has only the item number, the call may fail or return incomplete information. The underlying API may be working correctly, but the agent still cannot use it successfully because the contract was not satisfied.

This is why tool descriptions and parameter definitions are more than configuration details. They provide the context the agent uses when deciding how to work with its available capabilities.

In Oracle AI Agent Studio, tools can be configured and made available to agents. Topics and their instructions can add further guidance about the agent’s business scope and how capabilities should be used. The agent can also be configured with tools, topics, prompts, inputs, outputs, and interaction limits.

A poorly defined tool can therefore lead to poor agent behaviour even when the underlying API works perfectly.

Where Oracle AI Agent Studio fits

Oracle AI Agent Studio provides the environment for putting these pieces together. An agent can be given a business purpose, instructions, topics, and a set of tools. Those tools can expose capabilities from Fusion or from external systems.

For example, a Business Object tool can be used when the agent needs to work with supported Fusion business data. If the required capability is available through an API, an External REST tool can connect the agent to that service. AI Agent Studio also supports MCP tools and other capabilities such as document retrieval, connectors, email, and deep links.

These should not be thought of as three different versions of tool calling. They are different ways of exposing capabilities that an agent can use.

The important point is that the LLM does not need to directly implement communication with every backend system. Instead, the required capabilities are exposed through configured tools, and the agent can use their results as it continues working toward the user’s request.

Different tools, same pattern

The choice of tool depends on the capability the agent needs and where that capability or information is available.

Oracle AI Agent Studio provides different tools for different kinds of capabilities. A Business Object tool can work with supported Fusion business data, while an External REST tool can connect the agent to internal or external APIs. MCP tools provide another way to expose capabilities from external MCP servers. AI Agent Studio also provides tools for capabilities such as document-based retrieval, connectors, email, and deep links.

These are different tool types, but they fit into the same broader Tool Calling Pattern. The agent has access to a defined capability, determines when that capability is relevant to the task, provides the required inputs, and uses the returned result to continue working toward the user’s request.

A concrete tool-calling execution

It helps to follow one request all the way through rather than looking at tool calling as an isolated API operation.

Imagine the user asks: “Why is purchase order 1045 delayed? Check whether the required item is available in inventory.”

First, the agent identifies that the question requires current purchase-order information. It uses the appropriate Business Object capability and supplies the information needed to retrieve the purchase order.

Next, the returned purchase-order data gives the agent information about the item and organization involved. The agent can then determine that inventory information is required and use the appropriate configured tool with the relevant item and organization values.

The inventory result may show that the item is unavailable or that the available quantity is insufficient. The agent can then use both results to explain the likely reason for the delay.

The important part is that the next step can depend on the user’s request, the available tools, and the information returned by earlier steps. The agent uses those results to continue working toward the user’s request within its configured boundaries.

Tool calling is not the same as a workflow

This difference is easy to miss because both approaches can involve multiple steps.

A workflow normally has a known sequence. For example:

Extract invoice
↓
Validate invoice
↓
Update record
↓
Send notification

The developer defines that path in advance. Each step is expected to occur in a particular order.

With agentic tool calling, the capabilities used during a task can depend on the user’s request and the information available to the agent at that point. The agent still operates within its instructions, topics, tools, permissions, and interaction limits.

A simple way to remember the distinction is:

Workflow: the process is defined beforehand.

Tool calling: the agent uses available capabilities as needed within defined boundaries.

AI Agent Studio supports both approaches. Workflows are useful for predictable processes where the sequence is known. Agentic behaviour becomes useful when the information needed, or the steps required to reach an answer, can vary from one request to another.

The enterprise part: control matters

Giving an agent access to tools does not mean giving it unlimited access to the business. The tools available to the agent, the instructions controlling its behaviour, the user’s permissions, and the security of the connected system all matter.

There is also a practical difference between a capability that reads information and one that changes information.

Reading a purchase order is generally different from updating a purchase order, sending an email, or triggering a business operation. The second category can have consequences outside the conversation. For sensitive actions, AI Agent Studio supports human approval so that a person can review the operation before it is executed.

This leads to a useful principle for enterprise agents: the objective is not to give an AI agent maximum freedom. The objective is to give it the right capability with the right boundaries.

Tool design should therefore consider not only whether an operation works, but also who can use it, what it can change, what inputs it accepts, and whether a human should be involved before a sensitive action is completed.

When something goes wrong

Tool calling introduces another engineering challenge: debugging.

Suppose the agent produces an incorrect answer. The problem may not be the LLM itself. The agent might have selected an unsuitable tool, supplied an incorrect parameter, received an unexpected API response, or interpreted valid returned data incorrectly.

That means looking only at the final response is not enough. The complete execution path matters.

AI Agent Studio provides debugging capabilities that allow developers to inspect execution, context, inputs, outputs, and node behaviour. Developers can use breakpoints, step through execution, rerun parts of an execution, and inspect what happened during the process.

This changes the debugging question from “Why did the AI give me this answer?” to a more useful question: “Where did the execution go wrong?”

Was the request understood correctly? Was the appropriate tool selected? Were the parameters valid? Did the backend return what was expected? Did the agent interpret the returned data correctly?

Following the complete tool call makes these questions much easier to answer.

For example, if a tool returns no inventory records, the first assumption should not automatically be that the model failed. The input organization might be wrong, a required parameter might be missing, the backend response might not match what the agent expects, or the tool itself might not be the right capability for the request. Looking at the execution step by step helps separate these possibilities.

The bigger picture

Tool calling may sound like a small technical feature, but it is one of the pieces that makes agentic AI useful in enterprise applications.

Without access to appropriate tools or other external capabilities, an agent is limited in what current business information it can retrieve or what actions it can perform beyond the information available in its context. With tools, it can reach business systems, retrieve current information, interact with APIs, and perform controlled operations.

The real value, however, is not simply having more tools. An agent with dozens of poorly defined capabilities can be harder to control and debug than an agent with a smaller set of well designed ones.

What matters is having the right capabilities available, describing them clearly, supplying the right inputs, enforcing appropriate permissions, and allowing the agent to use them at the right point in a business task.

A useful way to look at the architecture is:

  • The model understands the request.
  • The tool exposes a capability.
  • The tool call connects the request to that capability.
  • The returned result gives the agent current information to continue reasoning.
  • The agent then turns those results into an answer or, where permitted, a controlled business action.

That is the practical shift from an AI that can tell you about the work to an AI that can actually participate in getting the work done.

The Machine was Running, it was just not producing

A treadmill can log eight miles of belt travel while you stand on the side rails. The console still claims motion. Your plant does the same thing when availability is the only number on the board.

The KPI is OEE (%), calculated as Equipment Availability × Performance Efficiency × Quality Rate (or First Pass Yield). Oracle Fusion Cloud Manufacturing already records the work order, resource usage, and quality inspection transactions that build all three factors at shift level, so supervisors can stop treating uptime as output and protect promise dates and backordered rate.

Plant boards still celebrate a green shift while promise dates slip and backorders climb. The gap is not missing sensors. It is reading only one of three factors. Availability alone does not equal output. Most plants instrument the first factor and leave performance and quality as monthly afterthoughts. The rest of this piece shows how the transactions you already post in Fusion turn that blind spot into shift-level action.

Why availability-only reporting hides real losses

Availability tells you the workstation reported as running. It does not tell you whether the line moved at the right speed or shipped good parts. That is why a full-shift green light can still leave the warehouse short and the customer waiting.

OEE (%) = Equipment Availability × Performance Efficiency × Quality Rate (or First Pass Yield). Equipment Availability reflects how much of the planned time the equipment actually ran. Performance Efficiency reflects whether it ran at the intended speed. Quality Rate reflects how much of the output was good the first time. The inputs behind all three already post in Oracle Fusion Cloud Manufacturing as work order, resource usage, and quality inspection transactions, and products needing rework pull the quality factor down.

Why a low number matters:

  • Low OEE reduces overall production effectiveness and limits output capacity.
  • It points to issues in equipment availability, performance speed, or product quality.
  • It raises production cost per unit through inefficiency and downtime.
  • It hurts delivery reliability and weakens competitiveness through lower operational efficiency.

Slow cycles and minor stops cut performance without ever flipping a downtime flag. The operator stays clocked in. The workstation status stays in-use. Yet each extra second per cycle compounds across hundreds of units until the shift finishes short of plan. Scrap and rework do the same to quality: the station looks busy while finished goods inventory does not grow.

Those hidden losses show up where COOs and CSCOs feel them. Completed quantities fall. Planners open expedites. Freight premiums rise. Promise dates move. Backordered rate climbs even though every availability report said the line was up. The same work order transactions that record status also hold the counts, cycle times, and inspection results that explain the shortfall.

Think of availability as the lights being on in a kitchen. Performance is ticket speed. Quality is plates that leave without coming back. You would never run a restaurant on lights alone (and yet many plants still do). Shift-level workstation data already captured in work order operations lets you read all three without bolting on another system.

Business Value Maximization (BVM) starts after go-live, when these derived metrics become decision tools rather than after-the-fact scorecards. The point is not a prettier chart. It is catching the loss while the shift still has hours left to recover.

What should you do with this framing on Monday morning? Stop accepting availability as a proxy for output. Ask which work centers report high uptime and still miss standard quantity. Those are your performance and quality leaks, and Fusion already holds the evidence.

The six big losses visible in Fusion transaction data

The classic six big losses are not a separate data project. They map to records Fusion already stores during execution: work order operations, resource usage, workstation status reason codes, and quality inspection results.

Break the losses into the three OEE buckets you will actually manage:

  • Availability losses: planned and unplanned downtime captured when operators change workstation status and assign a reason code.
  • Performance losses: slow cycles and minor stops revealed when ideal cycle time from the work definition is compared with actual runtime and total count.
  • Quality losses: scrap and rework recorded in inspection results against the quantities reported on the operation.

Reason codes assigned at the workstation level classify each stop so the loss type is not a matter of opinion after the fact. Oracle Fusion Cloud Manufacturing readiness documentation on workstation reason codes associates reason codes with workstation status and potential loss, and classifies stops as Availability Loss, Performance Loss, Not a Loss, or Break.

That classification is the difference between a vague “we had issues” note and a shift board that shows whether the hour was lost to a breakdown, a micro-stop, a scheduled break, or something that should not count against the line at all. Supervisors can aggregate the same codes from individual operations up to work center and plant views without new data collection. One operator’s reason code rolls into the work center card; work center cards roll into the plant view the operations leader reviews mid-shift.

A practical pattern we see: plants that only code major downtime bury performance loss inside “running” time. The minor stop never gets a code, so it never becomes a loss category, so it never gets a countermeasure. Once reason codes cover both availability and performance categories, the six big losses stop being a textbook slide and start being a filter on live transactions.

Use the codes as a shared language across shifts. If first shift codes a jam as performance loss and second shift codes the same event as a break, your plant roll-up lies. Align the code list at plant setup, train operators on when each code applies, and review a sample of coded stops in the first weeks after you turn the metrics on. The goal is clean classification, not more paperwork.

Once the codes and inspection results are trustworthy, aggregation is straightforward. Start at the operation, roll to the workstation, then the work center, then the plant. Each level answers a different question: which job is bleeding, which station needs help, which area is off plan, and whether the site will hit the day’s promise commitments.

Building availability, performance and quality from existing Fusion transactions

No additional sensors or side systems are required to derive the three factors. Planned production time and runtime come from shift-assigned work order operations. Ideal cycle time sits on the resource usage rate of the work order operation. Completed counts and inspection outcomes already post as part of normal execution.

Build the factors in this order so the math stays auditable:

  1. Equipment Availability: read planned production time against actual runtime for the shift window on that workstation or work center.
  2. Performance Efficiency: compare the ideal cycle time on the work definition with actual runtime and total count, so slow cycles and minor stops show up.
  3. Quality Rate (or First Pass Yield): compare good units with total units reported for the shift, treating rework and scrap as the drag.
  4. OEE (%): Equipment Availability × Performance Efficiency × Quality Rate for the current shift.

Oracle Fusion Cloud Manufacturing’s guide to monitoring workstations describes supervisors monitoring these metrics on the Production Supervision dashboard using data from work order operations, with ideal cycle time tied to the resource usage rate of the work order operation.

Products needing rework lower the quality value even when the station never went down. That is the quiet killer of promise dates: the line looks occupied while net good output falls behind the schedule the customer already heard.

Aggregate workstation metrics to work center and plant level for supervisor dashboards so you are not managing fifty cards with no roll-up. The same transaction set surfaces open exceptions that affect the current shift: missing assignments, overdue operations, quality holds, and status reasons that need a second look. Metric and root cause sit in one place, which is what makes the number actionable instead of decorative.

A common objection is “our rates are wrong, so OEE will be wrong.” Fair. Ideal cycle time only helps if the work definition reflects the real standard. Treat rate hygiene as part of the rollout. Confirm resource usage rates on the top volume operations first, then expand. Bad masters produce confident nonsense (we have all watched a dashboard defend a fantasy standard).

When the three factors are derived from the same work orders your planners already trust, OEE stops being a parallel science project. It becomes another view of execution truth you already pay to capture.

Moving from monthly reports to shift-level supervisor action

Monthly OEE roll-ups arrive after the expedite has already shipped and the margin is already gone. Real-time workstation cards replace those summaries with visibility a supervisor can use before the shift ends.

Configure performance metrics and reason codes at the plant level so deviations appear as soon as status and quantities post. The Production Supervision dashboard then displays plan adherence, OEE, availability, performance, and quality at work center and workstation level. That is the operating picture, not a weekend analytics export.

When Performance Efficiency drops mid-shift, the supervisor should not wait for a monthly deck. They should open the workstation card, read status and exceptions, and act.

Drill from the work center aggregate into individual workstation cards that show status, assigned operators, and open exceptions. Assign operators and operations at the workstation level to close gaps while hours remain. Each metric deviation should tie back to the specific work order operation causing the loss, so corrective action stays precise: move a skilled operator, clear a quality hold, recode a false downtime, or split an overloaded operation.

The levers that lift OEE are consistent across plants:

  • Improve operator efficiency so cycles run at the work definition’s intended speed.
  • Run WIP inspections so quality problems are caught at the operation, not at final inspection.
  • Reduce equipment downtime by coding every stop and removing the recurring causes first.

A simple shift rhythm keeps the dashboard from becoming wallpaper:

  • First hour: confirm assignments, open exceptions, and any workstation already off plan on availability.
  • Mid-shift: review performance and quality on the highest-volume work centers; rebalance labor where slow cycles cluster.
  • Final hours: protect promise-critical orders, clear rework queues that would otherwise miss packing, and lock reason codes so the next shift inherits clean history.

This is where post-go-live operations discipline matters more than another implementation workstream. The transactions are already flowing. The question is whether supervisors are expected to manage the three factors live, or only to explain last month’s chart in a conference room. Teams that treat the Production Supervision dashboard as a shift tool recover units the same day. Teams that treat it as a reporting curiosity keep buying back their own shortfalls with expedites.

If your plant still runs on end-of-month OEE, pick one work center and run the shift rhythm for two weeks. Compare completed good quantity and exception aging against the prior pattern. You do not need a plant-wide program to prove the point. You need one supervisor with clear codes, trusted ideal cycle times, and permission to reassign before the whistle.

For plants already live on Fusion and hunting measurable ROI rather than another module, process optimization work such as Second Sight sits inside the consulting engagement to tie these operating signals to outcome targets, not as a stand-alone product login.

How OEE shortfalls drive missed promises and backordered rate

Reduced performance and quality directly lower completed quantities per shift. Availability can look healthy while the plant still ships late, because the units that count are good units finished at the planned rate, not hours the station reported as busy.

Trace the path from factor to board KPI. A performance gap means fewer units per hour than the work definition assumed, so the schedule’s math no longer holds. A quality gap means some of those units return as rework or leave as scrap, so net supply to downstream operations and to the customer shrinks again. Stack both gaps across multiple workstations and the cumulative shortfall pushes promise dates out. The COO and CSCO then defend Improved Backordered Rate with a story that started as “the line was up.”

When losses stay unaddressed, planners resort to expedites. Premium freight, overtime, and hot-job disruption inflate cost and compress margin. The short-term save becomes the long-term habit. Backordered rate improves for a week, then returns, because the underlying OEE factors never changed.

The same Fusion data that calculates OEE also supports a forward view of backordered rate risk. If a work center sustains low performance or quality across successive shifts, completed supply will miss the demand already promised. You do not need a separate forecasting product to see the pattern: compare planned quantities on open work orders with good-unit actuals and open exceptions, then flag customer orders that depend on the lagging centers. That is enough to trigger recovery plans while recovery is still cheaper than apology.

Post-go-live value realization is the moment these derived metrics become decision tools. Implementation put the transactions in place. Value work makes supervisors, planners, and operations leaders use availability, performance, and quality as one conversation tied to promise dates. Orbrick’s work with manufacturers already live on Oracle Fusion Cloud centers on that outcome link: measurable movement on KPIs such as Improved Backordered Rate, not hours logged against a change request.

Edge cases still matter. A planned maintenance window coded correctly should not punish the line. A pilot run with intentionally slow cycles should not trigger the same escalation as a steady-state bottleneck. Reason codes and work order context keep those cases honest. The model fails only when every stop looks the same and every green availability score gets a free pass.

So what do you take to the next operations review? Bring one chart of availability-only history and one view of the three-factor OEE for the same work centers. Show completed good quantity beside backordered rate. The room usually stops arguing about whether the machines “ran” and starts asking which loss to remove first.

Conclusion

Shift-level OEE derived from the work order, resource and quality transactions already in Oracle Fusion Cloud Manufacturing turns the statement “the line was up” into the single number that protects promise dates and backordered rate. Read all three factors, code the losses honestly, and act inside the shift while recovery still changes the day.

We help manufacturers turn that number into sustained outcome gains through Business Value Maximization, including ongoing support paths such as Oracle Fusion managed services when the operating rhythm needs a steady partner after go-live.

Download the Tiny Transformations e-book to see how other teams connect execution metrics to board-level KPIs, then schedule a strategy session to map the same approach to your plant.